

JSTOR reported in January 2026 that 8 out of 10 users now get their answers directly within search interfaces, bypassing traditional website visits entirely. Read that again in the context of academic library licensing. If a researcher queries an AI system, gets a synthesized answer drawn from journal articles in a database the library subscribes to, and never clicks through to the journal platform — the COUNTER download event never fires. The usage stat is never recorded.
From the perspective of the library’s cost-per-download calculation, the content was never used. And yet it was used — perhaps more efficiently, more immediately, and at greater research value than the traditional click-and-read model it replaced. The library’s cost-per-download figure rises. This triggers a cancellation discussion. The subscription gets cancelled or scaled back. And the AI system that’s supposedly improving research productivity now has a narrower corpus to draw from. Nobody in this chain wins, and the metric system that is supposed to guide rational resource allocation decisions is leading everyone toward an outcome that harms the research enterprise. What is the resolution here? The only silver lining in this scenario is that this plays out with all database providers": We are all experiencing the same thing at the same time.
Key Data — Post 7: COUNTER Metrics & AI Intermediation
−22% Estimated decline in COUNTER download index from FY2021 peak to 2024 (index 2019=100: ~101 → ~78)
~55% Estimated share of actual research engagement with journal content that is invisible to COUNTER metrics in 2024–2025
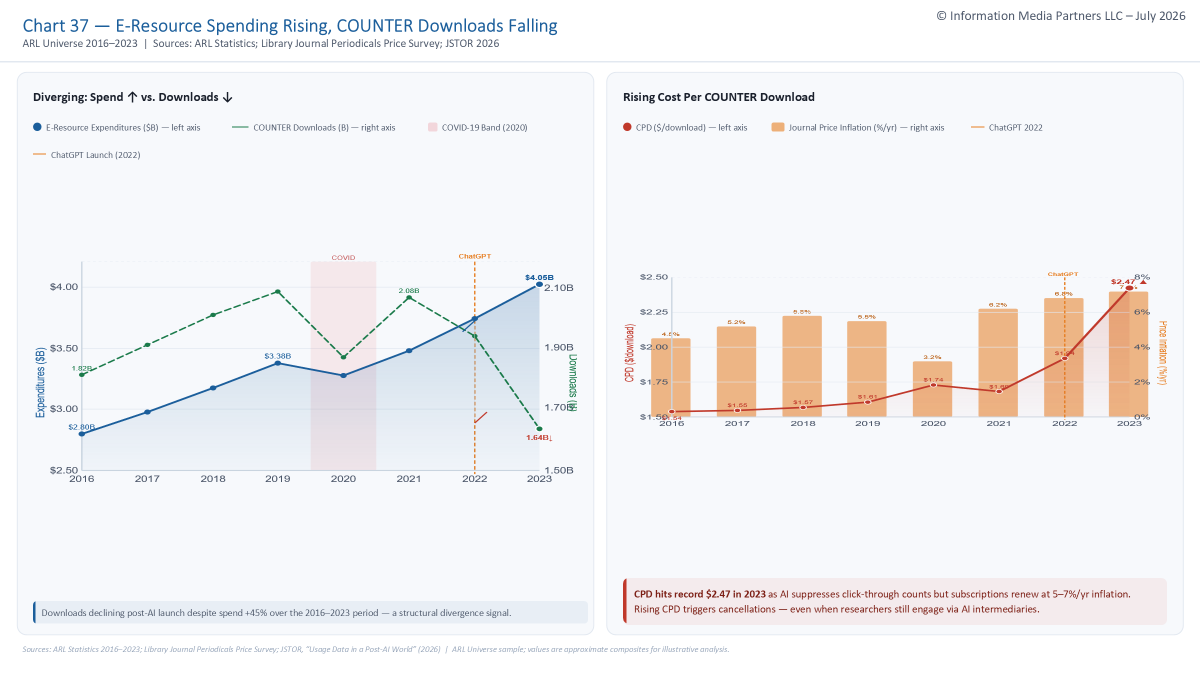
$2.47 Cost per COUNTER download in 2023 — a record high, up from $1.54 in 2016, driven by rising spend and declining counts
The Numbers: COUNTER Is Declining at the Worst Possible Moment
The estimated COUNTER downloads index — which tracks full-text article downloads from journal platforms, indexed to the 2019 baseline of 100 — rose to approximately 101 in FY2021 as COVID-driven research temporarily boosted platform access, but hen fell to approximately 78 by 2024 and a decline of approximately 22% from the FY2021 peak. Critically, it is happening at precisely the same moment as AI-powered research tools are experiencing explosive user growth. ChatGPT went from essentially zero weekly active users before November 2022 to 100 million within two months of launch — the fastest adoption of any consumer technology in history. Estimated weekly active users reached approximately 700 million by mid-2025. The coincidence of a sharp COUNTER decline and the explosive scaling of AI research tools is not a coincidence.
The cost-per-download arithmetic is where this hits libraries in practice. ARL e-resource expenditures grew from approximately $2.80 billion in 2016 to $4.05 billion in 2023, a nominal increase of 45%. COUNTER download volumes peaked around 2019 and have been declining since and I would argue a lot of this has to do with leakage. The reported ‘decline’ results in cost per COUNTER download rising from approximately $1.54 in 2016 to $2.47 in 2023 — a significant increase for a metric which is generally more stable year to year. The download figure is used in library collection management workflows as a primary indicator of subscription value. When the number rises above institutional thresholds — often set at $3.00–$5.00 per download depending on the institution and discipline — it triggers cancellation reviews. Libraries that are managing responsibly to what their data are telling them may be making cancellation decisions based on a metric that is, increasingly, measuring the artifact of AI intermediation rather than actual disengagement from subscribed content. On this basis, this scenario is also causing needless work for time strapped librarians.
The Measurement Gap: What COUNTER Counts vs. What’s Happening
COUNTER metrics may be understating research engagement at precisely the moment when academic publishers and libraries are relying on them most heavily for renewal decisions. Full-text downloads directly from journal platforms — what COUNTER measures — represent approximately 45% of total research engagement with subscribed content. AI-generated summaries on publisher platforms that include partial COUNTER tracking account for approximately 18%. AI chatbot responses that draw on article content but generate no platform visit account for approximately 22%. Search AI overview features that synthesize content without click-through account for approximately 10%. Cases where a researcher uses AI output derived from subscribed content and never visits the platform account for approximately 5%.
Adding the uncounted categories: an estimated 57% of actual research engagement with academic journal content is invisible to COUNTER metrics in 2024. Estimated COUNTER coverage of true research engagement has declined from approximately 95% in 2018 to 90% in 2020 to 72% in 2022 to approximately 45% in 2025. This data suggests a fundamental breakdown of the measurement infrastructure on which academic subscriptions are built.
These assessments are not coming from library advocates trying to argue against cancellations. National Bureau of Economic Research (NBER) Working Paper 34255 (Chatterji et al., September 2025) found that AI tools improve research productivity but reduce platform-level measured activity — precisely the dynamic described above. Scite.ai’s co-founder noted publicly in 2025 that “metrics are blind to how research articles are being used with AI.” When researchers and platform operators are making these observations independently, the measurement gap is real.
The Death Spiral Nobody Wants
AI reduces COUNTER download counts. Libraries cancel or scale back subscriptions based on CPD benchmarks that reflect AI intermediation rather than genuine research disengagement. Publishers lose subscription revenue. To compensate for revenue loss, vendors raise prices on remaining subscriptions. CPD rises further — both because prices are up and because COUNTER counts may continue to decline. More cancellations follow. And the AI systems that are now the primary research interface for many users may end up drawing on a narrower and narrower corpus of licensed content.
Nobody wins if this situation is not resolved as soon as possible. Publishers lose revenue and subscription relationships that took years to establish. Libraries lose breadth of access and face pressure to justify budgets with metrics that systematically underrepresent value. Researchers, faculty and students lose access to content their institutions once provided, often without understanding why. And the AI tools that are supposed to be improving research productivity end up operating on an increasingly constrained information base as libraries cancel the subscriptions from which that information came. This is a collectively irrational outcome driven by individually rational responses to a broken measurement system.
What Needs to Change Before the Next Renewal Cycle
COUNTER Release 5 improved methodology in important ways — particularly around deduplication and platform-level reporting standardization — but was developed before AI intermediation was a material factor in research behavior. COUNTER Release 6 will need to address AI from the ground up, not as an afterthought. That means building in tracking for API-level content access, synthesized content delivery events, and institutional IR-level access metrics. This is technically complex and will require cooperation from publishers who have institutional incentives to make their platform usage look as high as possible.
Publishers will need to sponsor and aid the development new metrics:
AI API call logs showing volume of content accessed via machine-readable interfaces
Content ingestion metrics tracking how often their licensed content is indexed or trained on by AI systems
Citation-in-AI-output tracking to measure how often AI-synthesized research responses cite their content
Institutional IR access metrics that capture total engagement across all discovery channels.
Libraries need to be in the room — actively, at the standards body level, at the contract negotiation table — as these metrics are developed. If publishers define the metrics unilaterally, they will define them in ways that serve publisher interests. That’s not a cynical observation; it’s a reasonable expectation of how institutions behave when measurement standards determine revenue.
Libraries also need contract frameworks that explicitly define what constitutes “usage” in an AI-mediated environment before signing the next Big Deal renewal. A contract that defines usage solely as COUNTER downloads is a contract that will increasingly misrepresent the value of the subscription in ways that disadvantage the library. Negotiating teams at major university systems should be raising this in every active renewal conversation.
The 2025–2027 outlook here is the most uncertain of any topic in this analysis. Major publishers — Elsevier, Springer Nature, Wiley — will almost certainly introduce proprietary AI-era usage metrics by 2026. Libraries should approach those metrics with healthy skepticism about what they measure, who controls the underlying data, and whether they are designed for mutual benefit or for revenue justification. And the fundamental question — what does a subscription actually buy you in a world where AI is the primary research interface for a growing share of your faculty and graduate students — will dominate academic library licensing negotiations for the foreseeable future.
We may be at the beginning of a process which results in the renegotiation of the entire academic publishing contract. The terms of the old contract were built around a specific (FTE) model of research behavior — a researcher sits at a terminal, searches a database, finds an article, clicks through to the full text, downloads a PDF — that process is rapidly being replaced by a very different model of AI-mediated research. It is entirely possible, that the AI managed research process results in deeper, broader access to subscribed content and not less as the COUNTER data suggests.
The data on all sides of this transition is becoming less reliable just as the stakes — billions of dollars in annual subscriptions, the research infrastructure of hundreds of universities, the information access of millions of researchers — are as high as they have ever been. Quickly addressing the COUNTER counting problem may be the most important unresolved challenge in academic information services over the next few years. Publishers, aggregators, platform providers and others will not wait and their actions to fill the counting gap may result in less understanding, less transparency and less trust.
Look for the next post in this series on the HR problems facing libraries. See the earlier posts for the intro to the series.
Full Library Presentation 2014 - 2023
Michael Cairns is a senior publishing executive and consultant. He can be reached at michael. cairns @ outlook.com or 908 938 4889